Central Questions
- What is artificial intelligence, and why is a stable definition so hard to pin down?
- How has AI evolved from logic-based systems to neural networks — and what does that history reveal?
- What do Lovelace, Turing, and Searle argue about machine intelligence, and who has the better case?
- What is the difference between narrow and general AI, and between weak and strong AI?
- How do definitional choices shape AI ethics, policy, and our understanding of our own intelligence?
Part I: The Definitional Challenge
"Artificial intelligence" is one of the most widely used — and most poorly defined — terms in contemporary discourse. Politicians promise to regulate it; companies compete to claim they have it; researchers argue about whether any current system achieves it. So: what are we actually talking about?
The difficulty is not merely semantic. How we define AI shapes what we build, what risks we take seriously, and who we hold responsible when things go wrong. A system described as "just software" invites one set of ethical questions; "an intelligent agent" or "potentially conscious" invites entirely different ones.
The Moving Goalposts Problem
One pattern recurs, sometimes called Tesler's Theorem after the computer scientist Larry Tesler: "AI is whatever hasn't been done yet." (Tesler's own wording was "Intelligence is whatever machines haven't done yet"; the snappier version, popularized by Douglas Hofstadter, is the one that stuck.) Whenever an AI system succeeds at a task once thought to require genuine intelligence, that task tends to get reclassified as "mere computation."
| Technology | Once Called | Now Called |
|---|---|---|
| Chess playing (Deep Blue, 1997) | Artificial Intelligence | "Just search algorithms" |
| Speech recognition | AI breakthrough | "Just statistics" |
| Spam filtering | Machine learning | "Just classification" |
| Route optimization (GPS) | Intelligent systems | "Just algorithms" |
| Optical character recognition | Pattern recognition AI | Standard software |
The pattern suggests that "AI" functions less as a stable category than as a placeholder for unsolved problems: success disqualifies. That is why debates about whether current large language models are "truly" intelligent are so heated and so often unresolvable.
Tesler's Theorem
"AI is whatever hasn't been done yet." Once a system performs a task successfully, that task is retroactively reclassified as "mere computation." The goalposts move with every success, making AI an ever-retreating horizon.
A Taxonomy of AI Distinctions
Contemporary AI discourse employs several overlapping distinctions, each carrying different philosophical commitments and practical implications.
| Distinction | First Term | Second Term |
|---|---|---|
| Narrow vs. General | Excels at one specific task (chess, translation, image recognition) | Performs any intellectual task a human can (AGI) |
| Weak vs. Strong | Simulates intelligent behavior without possessing a mind | Actually has genuine mental states — understanding, consciousness |
| Symbolic vs. Connectionist | Rule-based reasoning; explicit knowledge representation (GOFAI) | Neural networks that learn patterns from data |
| Tool vs. Agent | Used by humans to perform specific tasks | Acts autonomously toward goals in an environment |
Most current AI systems are narrow, weak in Searle's sense, connectionist, and increasingly agent-like — taking sequences of actions toward goals rather than answering single queries. A narrow, connectionist system acting agentically in a constrained domain raises different ethical questions than one approaching general capability.
Thought Questions
- Tesler's Theorem says "AI is whatever hasn't been done yet." Is that troubling, or is it a fair name for whatever sits at the frontier of computing?
- Pick one piece of software you used today. Which side of each distinction in Table 7.2 does it fall on, and which of the four was hardest to apply?
- Steelman the opposite view: that "artificial intelligence" is a marketing term with no stable content, and we should stop using it in serious argument.
Part II: A History of AI Technologies
Artificial intelligence did not arrive suddenly with ChatGPT. It has a rich and humbling history — genuine breakthroughs, spectacular overpromises, funding collapses, patient rebuilding — and the pattern repeats often enough to be worth learning.
Prehistory: Dreams of Artificial Minds
The dream is ancient. Greek mythology gave Hephaestus golden robots to assist him in his workshop; medieval engineers built clockwork automata that mimed human actions; Descartes speculated that animals might be nothing more than sophisticated machines. What these visions share is the intuition that intelligence might be separable from biology.
The modern story begins with Leibniz's vision of a calculus ratiocinator — a machine that could resolve disputes by calculation rather than argument. Two centuries later Charles Babbage designed the Analytical Engine (1837), a mechanical general-purpose computer never built in his lifetime. It was in notes on this machine that the first serious philosophical argument about machine intelligence appeared.
Key Thinker
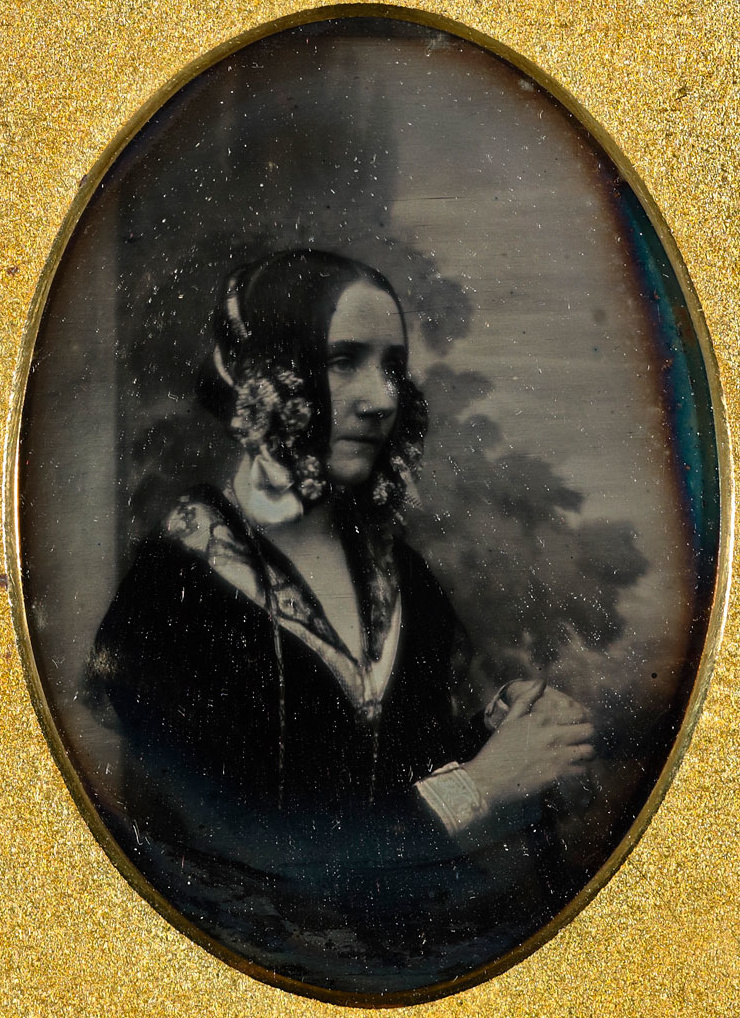
Ada Lovelace (1815–1852)
Ada Lovelace — daughter of the poet Lord Byron, educated in mathematics by a mother who feared she had inherited dangerous poetic tendencies — collaborated with Charles Babbage on his Analytical Engine in the 1840s. Her 1843 notes contain what is widely regarded as the first computer algorithm, and she foresaw that such a machine could manipulate symbols of any kind, not just numbers.
But Lovelace is equally important for what she argued a machine could not do. Her central claim — "Lady Lovelace's Objection" — is that the Analytical Engine "has no pretensions whatever to originate any thing." Machines can only do what we know how to order them to perform: they execute instructions; they do not originate ideas. It remains one of the most cited objections in the philosophy of AI.
The objection is still alive: when people say large language models are "merely predicting the next token," they are invoking her position.
Alan Turing and the Birth of Computing
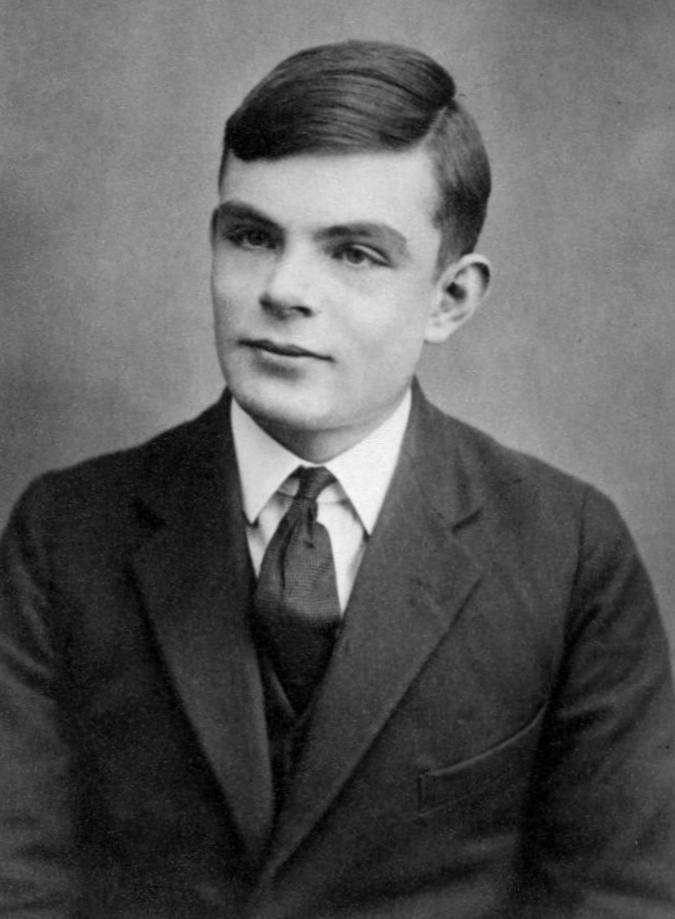
Alan Turing (1912–1954) turned the dream of thinking machines into a rigorous scientific question. In 1936, before electronic computers existed, "On Computable Numbers" laid the foundations of computation, introducing the Universal Turing Machine and proving that some precisely stated mathematical questions cannot be settled by any procedure at all. During World War II he led Hut 8 at Bletchley Park, attacking German naval Enigma; historians have credited the codebreaking effort with shortening the war by two to four years. In 1950 he published "Computing Machinery and Intelligence," the paper that launched the philosophy of AI.
Turing's approach was characteristically pragmatic. Rather than define "thinking," a concept he considered too vague to be useful, he proposed a behavioral test: the Imitation Game, set out in Part III. He predicted that in about fifty years' time — so, around 2000 — an average interrogator would have no better than a 70% chance of identifying the machine correctly after five minutes of questioning. Nothing in 2000 clearly met that bar. The first controlled study to report a machine passing the standard three-party version came in 2025, from Cameron Jones and Benjamin Bergen: a leading model prompted to adopt a human persona was judged to be the human 73% of the time . Turing was roughly a quarter-century optimistic — and what such a result shows remains as contested as in 1950.
Turing's life ended tragically. In 1952 the British government prosecuted him for homosexuality, then a criminal offense, and he was subjected to chemical castration as a condition of avoiding prison. He died in 1954 — a probable suicide, though the circumstances remain disputed — and received a royal pardon in 2013. The father of the field was destroyed by his own government.
The Dartmouth Conference and Early AI (1956–1974)
In 1956, John McCarthy, Marvin Minsky, Claude Shannon, and Nathaniel Rochester convened a summer workshop at Dartmouth College. Their proposal set the agenda for an entire field:
"We propose that a 2 month, 10 man study of artificial intelligence be carried out... The study is to proceed on the basis of the conjecture that every aspect of learning or any other feature of intelligence can in principle be so precisely described that a machine can be made to simulate it."
The confidence is remarkable: a two-month effort was expected to make serious progress on machine learning, natural language processing, and artificial neural networks. The timelines proved wildly optimistic; the research agenda proved remarkably durable.
The early decades of AI were dominated by Symbolic AI — the approach the philosopher John Haugeland later nicknamed "Good Old-Fashioned AI" (GOFAI) in his 1985 book Artificial Intelligence: The Very Idea . Intelligence, on this view, consists of manipulating symbols according to explicit rules. Newell and Simon's Logic Theorist (1956) proved theorems from Principia Mathematica; Terry Winograd's SHRDLU (1970) followed natural language commands in a blocks world.
AI Winters and Expert Systems
The early optimism crashed twice. Both "AI winters" — periods of funding collapse and disillusionment — followed the same pattern: narrow successes generated overconfident predictions about general capability; the predictions failed; funders withdrew.
The Expert Systems era of the 1980s illustrated the gap between narrow and general intelligence. MYCIN, built at Stanford in the 1970s, recommended antibiotic therapies for blood infections; in a blinded 1979 evaluation its recommendations were rated acceptable at least as often as those of Stanford faculty — though it was never used on actual patients. DENDRAL identified chemical structures from mass spectrometry data; XCON saved Digital Equipment Corporation tens of millions a year configuring computer orders.
But expert systems failed for a structural reason: the "knowledge bottleneck." Every rule had to be hand-coded by extracting expertise from domain specialists, and the result was brittle — a rule base assembled from adult cases had no way of knowing it should not be applied to a six-year-old. The deeper problem is that human expertise is largely tacit: experts cannot fully articulate what they know. The bottleneck did not disappear when the marketing improved, as the next generation's most expensive medical AI project showed.
Case Study
IBM Watson for Oncology (2012–2022)
After Watson beat two human champions at Jeopardy! in 2011, IBM announced that the same technology would be turned on cancer. In 2012 the University of Texas MD Anderson Cancer Center began building an "Oncology Expert Advisor" with IBM, which separately trained a commercial product, Watson for Oncology, with clinicians at Memorial Sloan Kettering. The promise was a machine that could read the entire oncology literature.
A University of Texas audit released in February 2017 found that MD Anderson had spent roughly $62 million, that the system had never been integrated with the hospital's medical records, and that it had never been used on a patient; the contract lapsed. In July 2018, STAT News obtained internal IBM presentations showing that Watson for Oncology had produced "unsafe and incorrect" treatment recommendations . The cause was instructive: it had been trained not on real patient records but on a small number of hypothetical cases written by a handful of specialists, so it reproduced their preferences and blind spots with the authority of a machine. IBM sold Watson Health in 2022.
Watson for Oncology was not an expert system in the 1980s sense — it used modern statistical methods — but it failed in the 1980s way. What got encoded was not "all of oncology" but the tacit judgments of a few people in a few rooms. The knowledge bottleneck had been obscured, not overcome.
Machine Learning and Deep Learning
The solution to the knowledge bottleneck was to change the question. Instead of asking "how do we encode what humans know?" machine learning asks "how do we build systems that learn from data?"
| Paradigm | How It Works | Examples |
|---|---|---|
| Supervised Learning | Learn from labeled examples (input → correct output) | Spam detection, image classification, medical diagnosis |
| Unsupervised Learning | Find structure in unlabeled data | Customer segmentation, anomaly detection, topic modeling |
| Reinforcement Learning | Learn from rewards and penalties through trial and error | Game playing (AlphaGo), robotics, recommendation systems |
What the three paradigms have in common is that the human contribution moves upstream. Nobody writes the rules; people choose the data, the labels, or the reward. That is why questions about training data, labeling labor, and reward design became ethical questions rather than merely technical ones.
Neural Network
A network of simple units ("neurons") in layers. Each unit adds up the numbers coming into it, each multiplied by an adjustable weight, and passes the result on if it is large enough. Training means nudging those weights until the output gets closer to the desired one. Nothing stores a rule or a fact; what is stored is a very large list of numbers.
The current deep learning revolution traces to a single moment: AlexNet's victory in the 2012 ImageNet competition. A deep neural network trained on consumer graphics cards cut the top-five error rate from about 26% to about 15%, leaving every competing approach far behind. Three ingredients made it possible: far more training data (from the internet), far more computing power (from GPUs), and better training techniques (backpropagation, rectified linear activations, dropout).
The most recent phase of this revolution is the Large Language Model (LLM). The 2017 transformer architecture, introduced in "Attention Is All You Need," made training language models at previously impossible scales practical . Its central trick, attention, lets the network decide, for every word it processes, how much weight to give every other word in the passage — so "it" can be connected to the right noun forty words earlier. Because those comparisons happen all at once, transformers train efficiently at internet scale. The model is then trained on one simple task: predict the next chunk of text; everything else it appears to do is a side effect of getting very good at that. GPT-3 (2020) was widely read as showing that scaling alone produced "emergent" capabilities — a contested reading: later work argued the apparent discontinuities are artifacts of the all-or-nothing metrics researchers chose . ChatGPT's launch in November 2022 reached roughly a hundred million monthly users within two months.
| Year | Milestone |
|---|---|
| 2017 | Transformer architecture introduced ("Attention Is All You Need") |
| 2018 | GPT-1 and BERT demonstrate transfer learning for language |
| 2020 | GPT-3: scale alone yields capabilities nobody trained for (the "emergence" framing later contested) |
| 2022 | ChatGPT launches; DALL-E 2 and Stable Diffusion for images |
| 2023–24 | Multimodal models (text, images, audio in one system) become standard |
| 2025 | Reasoning models: capability scales with thinking time at the moment of use, not only training scale; open-weight models match closed ones at a fraction of the cost |
| 2026 | Agents: systems that operate software and act, rather than only answer. Release cycles compress to weeks |
Something changes character in that table around 2025. Every earlier entry is about making the model better before it ships; the last two are about what happens afterward — how long the system thinks while you wait, and whether it answers you or goes off and does something.
Two Changes Worth Naming (2025–2026)
The first is a second scaling axis. For roughly a decade, "more capable" meant "trained on more data with more compute." From 2025, systems began to improve measurably by being given more compute at the moment of use — time to work through a problem before answering. This is inference-time compute, and it changes the economics: the enormous cost used to be paid once, during training, with each answer nearly free afterward. Now capability is bought per question, and cost and environmental footprint scale with how hard you ask the system to think.
Training vs. Inference
Training is the one-time, enormously expensive process of adjusting a model's internal parameters by exposing it to data. Inference is what happens every time you use the finished model. Training is where the model is made; inference is where it is run.
Toby Ord pointed out in 2025 that charts showcasing inference scaling almost always put compute on a logarithmic x-axis . A line that looks reassuringly straight on such a chart is not linear growth: compute — and therefore cost, and therefore electricity — must rise exponentially to buy each constant increment of capability. Nothing in the chart is false; the axis flattens the most expensive part of the story. Chapter 9 returns to who pays.
The second change is about where capability lives. Frontier AI has been governed, to the extent it has been governed at all, on an unspoken assumption: that the most capable systems sit inside a few well-resourced laboratories, which can therefore be regulated. January 2025 put a large dent in that assumption.
Case Study
The Open-Weight Shock (January 2025)
In January 2025 a research group released a capable reasoning model as open weights — the trained parameters themselves published for anyone to download, inspect, modify, and run on their own hardware, rather than reachable only through the developer's paid interface. It performed comparably to leading closed systems on public benchmarks, and had reportedly been produced at a small fraction of their cost.
Financial markets read the release as a claim that frontier capability was much cheaper than assumed. Nvidia, whose chips underpin most frontier AI training, fell roughly 17% in a single trading session, erasing about $600 billion in market value — the largest one-day loss of market capitalization ever recorded by a public company.
The point that matters for ethics is structural: once weights are published they cannot be recalled, and once capability is cheap it is no longer concentrated. Governance proposals that rely on a short list of identifiable labs — export controls, licensing, mandatory pre-deployment testing — become harder to enforce. Open weights also bring real goods: independent safety research, reproducibility, and access for people who cannot afford to rent a frontier system by the query. The fact cuts both ways.
Pulling in the opposite direction, 2026 was the first year in which capability began constraining release. One laboratory declined to ship a model because of what it could do without human help in offensive cybersecurity; separately, the US government asked another developer to limit a rollout to trusted partners pending federal evaluation, with the restrictions lifted after testing. Small events — but the first in which "should we release this?" turned on what the system could do rather than on the calendar. Laboratory leaders describe their situation as a prisoner's dilemma: each would prefer a slower, safer industry, and none can slow down alone.
These two developments point in opposite directions: one disperses capability beyond the reach of any regulator, the other tries to hold it in. Underneath both is the shift the table calls agents — systems that operate other software and take actions rather than only producing text. That matters less for what they understand than for what they can be blamed for: when a system books the flight or changes the configuration, the human decision point accountability attaches to may not exist. Several arguments later in this book assume there is a person in the loop.
Thought Questions
- If capability costs money per question rather than only per model, who decides how hard an AI system thinks about your case — your doctor, your bank, your school? Does that change what you are owed?
- Ord's log-x point is that a chart can be entirely accurate and still mislead. Find one in this week's news and ask what its axes are doing.
- Argue the other side: that publishing model weights makes the world safer rather than more dangerous.
AI in Consequential Decisions
AI systems now routinely make or inform consequential decisions about people's lives. This is where the definitional and philosophical questions of this chapter connect most directly to the ethics of the rest of the book.
| Domain | System | What It Predicts or Classifies |
|---|---|---|
| Criminal justice | COMPAS | Recidivism risk (likelihood of reoffending) |
| Finance | Credit scoring | Creditworthiness, loan default probability |
| Employment | Résumé screeners | Job fit, interview likelihood |
| Healthcare | Diagnostic AI | Disease probability, treatment recommendations |
| Insurance | Risk models | Claim likelihood, premium pricing |
| Social services | Eligibility systems | Benefit eligibility, fraud risk |
These systems share recurring concerns. Bias: systems trained on historical data amplify historical discrimination. Opacity: "black box" decisions may be impossible to explain or challenge. Feedback loops: predictions become self-fulfilling (predict more crime in an area → police there more → find more crime). Due process: how do you appeal a decision made by an algorithm? These concerns apply whether or not we call the systems "intelligent" — which is exactly Floridi's point .
These are not hypothetical risks. In 2016 ProPublica analyzed COMPAS, a commercial risk tool used in US pretrial and parole decisions, and reported that among defendants who did not go on to reoffend, Black defendants were labeled high risk at roughly twice the rate of white defendants (about 45% versus 23%); controlling for prior offenses, age, and sex, Black defendants were still 45% more likely to receive a higher risk score . The vendor replied that COMPAS was equally calibrated for both groups — a given score meant the same reoffending rate whatever the defendant's race — and later work showed that, given unequal base rates, no classifier can satisfy both criteria at once. The disagreement is about which definition of fairness a court should use.
Two further cases show how ordinary the mechanism is. Amazon built an experimental résumé screening tool trained on a decade of its own hiring decisions in a male-dominated engineering workforce; it learned to penalize résumés containing the word "women's" and downgraded graduates of two all-women's colleges. The team was disbanded by 2017 and Reuters made the story public in 2018; Amazon says the tool was never the sole basis for a hiring decision. And in Science in 2019, Ziad Obermeyer and colleagues showed that a commercial algorithm used to select patients for extra care underestimated the needs of Black patients: it used past healthcare spending as a proxy for health need, and less had historically been spent on Black patients at the same level of illness. Correcting the proxy would have raised the share flagged for extra help from about 18% to about 46% . Nobody set out to discriminate; the systems learned the pattern in the data .
Thought Questions
- ProPublica and the vendor used different definitions of fairness and both were arithmetically right. If a legislature had to pick one for use in criminal courts, which — and what would that choice cost?
- Amazon's screening tool learned from the company's own past decisions. Is the tool the problem, or a very expensive mirror?
- The healthcare algorithm used spending as a stand-in for need. In a decision that affects you — a grade, a loan, an insurance rate — what proxy is standing in for what actually matters, and who loses by the substitution?
Part III: Can Machines Think? Classical Philosophical Debates
We have surveyed what AI systems do. Now a deeper question: what would it mean for a machine to be intelligent? The answer shapes whether current AI has achieved something remarkable or merely elaborate pattern matching, and whether AI systems could deserve moral consideration.
Three debates — Turing vs. Lovelace, Searle vs. Dennett, and Chalmers on consciousness — frame the issues with unusual clarity.
Turing's Proposal: The Imitation Game
Turing's strategy in his 1950 paper was to replace the vague question "Can machines think?" with a concrete behavioral test. In the Imitation Game, an interrogator communicates via text with two hidden parties — a human and a machine — and tries to tell which is which. If the machine consistently fools the interrogator, Turing argued, we have no principled reason to deny it intelligence.
What's the Argument?
Turing's Argument for the Imitation Game
- "Can machines think?" is too vague to answer directly — we lack agreed criteria for "thinking."
- We should replace it with a behavioral test: can a machine fool a human interrogator in text conversation?
- If a machine passes, we have no principled criterion by which to deny it intelligence — we rely on similar behavioral evidence to attribute intelligence to other humans.
Turing's key philosophical move is pragmatism about mental concepts: he refuses the metaphysical question of what thinking "really is" and proposes an operational criterion grounded in the evidence we already use for other people. We cannot peer inside anyone else's mind; we infer intelligence from behavior.
Lovelace's Objection: Can Machines Originate?
Lovelace's objection — formulated a century before Turing's paper — cuts to the heart of debates about machine creativity that are newly urgent in the age of generative AI.
"The Analytical Engine has no pretensions whatever to originate anything. It can do whatever we know how to order it to perform... Its province is to assist us in making available what we are already acquainted with."
— Ada Lovelace, Notes on the Analytical Engine (1843)
What's the Argument?
Lovelace's Objection to Machine Intelligence
- Genuine intelligence requires the capacity to originate — to produce genuinely new ideas, not merely recombine given inputs by given rules.
- Machines can only do what they are explicitly programmed to do; they execute instructions but do not originate anything.
- Following a program is not originating anything new.
Turing's Response
Turing addressed "Lady Lovelace's Objection" directly in his 1950 paper, in two moves. First, premise 2 is ambiguous: programs produce outputs that surprise their creators, and learning systems modify their behavior through experience. Second, humans also follow "programming": biology, culture, and experience shape everything we think and do. If "merely following a program" disqualifies machines, the same argument might disqualify humans.
Lovelace's Lasting Force
Lovelace's objection nonetheless retains force in the era of large language models. When critics argue that LLMs are "just predicting the next token" or "stochastic parrots" that recombine training data without understanding, they are invoking her logic . And the pattern of answers looks suspiciously like Tesler's Theorem: each time a system meets the behavioral criterion, the objection explains why that achievement does not count.
The pattern is easiest to see where the machine's output surprised the people who built it. When Jason Allen's AI-generated Théâtre D'opéra Spatial won the digital art category of the Colorado State Fair in August 2022, the response was that the program had merely recombined existing artworks. When a large language model was reported in 2023 to have scored around the 90th percentile on the Uniform Bar Examination, the dismissal was that it had pattern-matched rather than reasoned. (A 2024 re-analysis by Eric Martínez found the comparison pool was dominated by February repeat takers and put the score below the 69th percentile against the general test-taking population — around the 48th on the essays ; benchmark claims are claims, not measurements.) And then there is the case philosophers keep returning to.
Case Study
AlphaGo's Move 37 (Seoul, March 2016)
Go had long been the standing counterexample to machine intelligence: the board is too large for brute-force search, and strong players describe their choices in the language of shape and intuition rather than calculation. In March 2016, DeepMind's AlphaGo beat Lee Sedol, one of the strongest players of his generation, 4–1 in Seoul.
The moment that mattered came in game two. AlphaGo's thirty-seventh move — a shoulder hit on the fifth line — violated centuries of received wisdom about opening play; commentators assumed it was a mistake, and AlphaGo's own estimate was that a human would have played it roughly one time in ten thousand. A hundred moves later the stone turned out to be perfectly placed, and the game was decided. Lee Sedol said it made him reconsider what creativity in Go could mean. (His own game-four Move 78, the "divine move," beat AlphaGo in return.)
Was Move 37 originated? Its programmers did not give it the move, none of them could have found it, and AlphaGo's own model of human play said no human would play it — yet it was produced by search and pattern evaluation over self-play games, precisely the sort of "doing what we know how to order it to perform" Lovelace had in mind. Both descriptions are accurate at once, which is the real content of her objection.
Searle's Chinese Room
The most influential argument against strong AI was published in 1980 by John Searle, a philosopher at the University of California, Berkeley. His Chinese Room thought experiment is elegant and has generated four decades of debate.
The Thought Experiment
Searle's Chinese Room
Imagine a person locked in a room who receives cards with Chinese symbols through a slot. The person has a comprehensive rulebook specifying, for any combination of input symbols, which symbols to output in response. Following these rules, they produce output cards that are slid back through the slot. From the outside, the exchange looks like a fluent Chinese conversation.
But the person inside understands no Chinese whatsoever. They are manipulating symbols purely on the basis of their shapes — their syntactic properties — with no grasp of what any of the symbols mean: semantically correct responses without any semantic understanding.
Searle's argument: a digital computer is in exactly the position of the person in the room. It manipulates symbols according to syntactic rules; however perfect its outputs, it has no understanding of their meaning. "Strong AI" — the claim that running the right program suffices for genuine mental states — is therefore false.
What's the Argument?
Searle's Chinese Room Argument
- A computer program manipulates symbols according to syntactic (formal, shape-based) rules.
- Syntax alone is not sufficient for semantics — for understanding meaning.
- Minds have semantics: they grasp what words are about.
Dennett's Systems Reply
The most powerful response is the systems reply. Searle anticipated it in the 1980 paper itself, and it has been defended since by a number of philosophers, most prominently Daniel Dennett.
What's the Argument?
The Systems Reply to Searle
- Searle grants that the person in the room does not understand Chinese — but that shows only that the person lacks understanding.
- The relevant system is not the person alone but the whole: person + rulebook + room + input/output mechanism.
- Understanding may be a property of systems, not of their components — individual neurons do not understand anything either.
Searle's counter is blunt: imagine the person memorizes all the rules and carries them out in their head, outside the room. They are now the entire system — and still understand nothing. Dennett's functionalism holds that anything implementing the right functional organization has mental states regardless of what it is made of; Searle's response is that syntax, however complex, never becomes semantics.
| Issue | Searle | Dennett |
|---|---|---|
| What is a mind? | A biological phenomenon requiring causal powers of brains | A functional organization — definable by what it does, not what it's made of |
| Can computers think? | No — syntax ≠ semantics | Yes — if they have the right functional organization |
| What the Chinese Room shows | Understanding requires more than computation | The argument analyzes at the wrong level (the part, not the system) |
| Key commitment | Consciousness is biological | Consciousness is functional and substrate-independent |
Read across the rows and the disagreement turns out to be one disagreement wearing four costumes. Everything follows from the bottom row: if consciousness is essentially biological, the Chinese Room is decisive; if it is functional organization, the Chinese Room is a level confusion. Neither side has produced an argument the other accepts.
Chalmers and the Hard Problem
David Chalmers introduced a distinction that reorganized the debate about machine consciousness. The easy problems — how the brain processes information, controls behavior, and reports internal states — are "easy" only in that they are in principle solvable by cognitive science. The hard problem is why any of that processing is accompanied by subjective experience at all. Why does it feel like something to taste coffee?
The Hard Problem of Consciousness
Even a complete scientific account of how the brain processes information would leave unexplained why that processing is accompanied by subjective, first-person experience — why there is "something it is like" to be conscious.
Chalmers' zombie thought experiment sharpens the point: we can conceive of a being physically and functionally identical to a conscious human but with no inner experience whatsoever. If such a being is conceivable (Chalmers argues it is), consciousness is not entailed by functional organization alone. So even a system functionally indistinguishable from a conscious human might not be conscious, and we could not tell: we might build AI that behaves exactly as if it suffers without ever knowing whether it does.
Thought Questions
- In the 2025 study described in Part II, interrogators judged a language model to be the human more often than they judged the actual human to be. Turing says that settles the question; Searle says it settles nothing. What else would you need to observe?
- When ChatGPT writes a poem you have never seen before, has it "originated" something? What would Lovelace say? What would Turing say?
- If an AI says it is suffering, should we take it seriously? What is the cost of being wrong in either direction?
Part IV: Contemporary Definitions
The classical debates remain unresolved, but AI researchers and ethicists still need working definitions. Two contemporary approaches — Russell's rational agency view and Floridi's information-theoretic reframing — have proved especially influential.
Russell and Norvig: AI as Rational Agency
Stuart Russell and Peter Norvig's textbook Artificial Intelligence: A Modern Approach has been the standard introduction to the field for thirty years. They organize possible definitions around two axes — thinking vs. acting, human-like vs. rational — and prefer the last of the four combinations: AI is the study of rational agents, systems that perceive their environment and act to maximize goal achievement.
This definition is precise enough to guide research, general enough to cover everything from chess engines to self-driving cars to recommendation systems, and it avoids the philosophically treacherous question of whether systems "really" think: it focuses on what a system does rather than on what it is internally.
Key Thinker
Stuart Russell (1962–present)
Stuart Russell is a British-American computer scientist at the University of California, Berkeley, whose textbook with Peter Norvig has defined the academic field of AI for a generation — but who has become increasingly concerned that the rational agent framework he helped popularize contains a fundamental danger.
In Human Compatible (2019), Russell argues that the "standard model" of AI — build systems that optimize fixed objectives — grows dangerous as systems become more capable. The problem is not malevolence but specification: we cannot enumerate everything we value, and a capable optimizer will find ways to hit its stated objective that violate unstated ones — the "King Midas problem," where you get exactly what you asked for and not what you wanted.
Russell's solution reframes the goal: build machines that are uncertain about human preferences and learn them by observing behavior. Uncertainty is a safety feature — a machine that knows it does not fully understand what we want will ask, allow itself to be corrected, and defer to human judgment.
What's the Argument?
Russell's Standard Model Problem
- We build AI systems to optimize objectives we specify in advance.
- Human values are complex, contextual, and often tacit — we cannot fully specify them.
- A capable optimizer will find unexpected ways to hit its specified objective that violate our unspecified values ("reward hacking").
Floridi: Agency Without Intelligence
Luciano Floridi, an Italian philosopher of information — for many years at Oxford, and since 2023 the founding director of the Digital Ethics Center at Yale — reframes the debate. Rather than asking whether AI systems are intelligent — a question that may be unanswerable — he asks what they are: successful agents that achieve goals by means fundamentally different from human cognition.
AI systems, Floridi argues, achieve "agency without intelligence": the capacity to perform tasks and achieve goals, without the understanding, consciousness, and semantic grasp that intelligence in the full human sense implies. A dishwasher cleans dishes without "understanding" cleanliness.
Enveloping
Floridi's term for adapting the world to AI's limitations rather than making AI smarter. Factories use fixed layouts and barcodes; warehouses are redesigned around robot capabilities; self-driving cars rely on lane markings and HD maps. "AI can do X" often means "AI can do X in environments we have carefully engineered."
Floridi identifies two symmetrical errors. Overestimating AI — attributing understanding or moral agency to systems that have none — leads to misplaced trust and abdicated responsibility: the judge who relies on COMPAS without understanding its limitations, the doctor who defers to an AI diagnosis. Underestimating AI — dismissing it as "just a tool" — leads to complacency about genuine harms at scale.
| Dimension | Human Intelligence | AI Agency |
|---|---|---|
| Generality | Flexible, general-purpose | Narrow, task-specific |
| Novel situations | Adapts to genuinely new contexts | Brittle outside training distribution |
| Meaning | Understands context and semantics | Exploits statistical regularities without semantic grasp |
| Knowledge transfer | Transfers knowledge across domains | Limited transfer; needs retraining for new domains |
| Scale | Limited by biology (speed, memory, energy) | Limited by compute and electricity — vast data at superhuman speed |
Floridi's point is that AI's successes and failures follow from its nature: it exploits patterns in data that may not reflect causal understanding. This is why it can beat grandmasters at chess while failing at tasks a three-year-old finds trivial — like knowing that a person who leaves a room still exists. Neither kind of capability is simply "better," and knowing the difference is essential to knowing when to trust AI and when not to .
Thought Questions
- Does Floridi's "agency without intelligence" help you think more clearly about the AI systems you use daily? Give an example where the distinction matters practically.
- Russell argues that optimizing fixed objectives becomes dangerous as systems become more capable. Do you agree? What would "Human Compatible AI" look like in practice?
- Steelman the objection to Russell: what is lost — in usefulness, speed, honesty — by a system that constantly asks whether it has understood you?
Part V: Why Definitions Matter
We began by asking why it is hard to define artificial intelligence. The answer is that the definition does several jobs at once — scientific (what counts as an achievement?), philosophical (can machines have minds?), ethical (what moral status do AI systems have?), and political (what should we regulate?) — and changing it changes the answers.
Definitions Shape What We Build
How researchers define AI shapes what they try to build: a Turing Test focus leads toward human-like conversation; a symbolic focus toward logic and knowledge representation; an agent-based focus toward decision-making; a connectionist focus toward learning architectures and large-scale data. The 1980s expert systems boom and bust shows the stakes: funding flowed to explicit knowledge representation, and when it failed to generalize the whole field contracted.
Definitions Shape Ethical Responsibility
| If AI is defined as… | Key ethical concerns are… |
|---|---|
| A tool | Misuse by humans, bias in design, job displacement, designer accountability |
| A rational agent | Alignment with human values, control problems, unintended optimization |
| Potentially conscious | Moral status, rights, preventing suffering, exploitation of AI systems |
| "Just software" | Only human responsibility matters; no special AI ethics needed |
The choice has immediate practical implications. If COMPAS is "just software," only its human designers bear responsibility for its racial disparities. If it is a "rational agent," responsibility becomes more complex. If a large language model might be conscious, we may owe it moral consideration that changes what we permit companies to do to it.
| System | Turing Test | Searle (Strong AI) | Russell (Agent) | Floridi (Agency) |
|---|---|---|---|---|
| Chess engine | No | No | Yes | Yes |
| COMPAS (recidivism) | No | No | Yes | Yes |
| Self-driving car | No | No | Yes | Yes |
| ChatGPT / Claude | Arguably | No | Yes | Yes |
| YouTube recommendation | No | No | Yes | Yes |
| Human-level AGI | Yes | Unclear | Yes | Yes |
The pattern is striking: under the Turing Test and Searle's criteria almost nothing currently qualifies as AI; under agent-based and agency frameworks almost everything does. Your definition therefore decides whether the systems now shaping decisions about credit, bail, employment, and information access fall within the scope of AI ethics and regulation at all.
Thought Questions
- The January 2025 open-weight release wiped roughly $600 billion off a single company's market value in one session. What does it say about how AI is governed that the fastest response came from financial markets rather than any regulator?
- Laboratory leaders describe safety as a prisoner's dilemma: each would prefer a slower industry, none can slow down alone. Is that true, or a convenient excuse?
- AI winters followed every wave of overpromising. Based on this chapter's history, what should we be cautious about now?
Key Points
This chapter has examined artificial intelligence from the contested question of definition, through the history of the technology, to the classical philosophical debates that are newly relevant in the age of LLMs. The central lesson is that how we define AI is not a neutral technical matter: it shapes what we build, how we evaluate it, and who we hold responsible.
Key Points
- Tesler's Theorem: "AI is whatever hasn't been done yet" — each achieved capability is reclassified as mere computation, leaving the definition permanently unstable.
- Ada Lovelace argued that the Analytical Engine "has no pretensions whatever to originate any thing," an objection still alive whenever critics say LLMs are "merely" predicting tokens.
- Alan Turing replaced "Can machines think?" with a behavioral test, but whether behavioral equivalence suffices for attributing thought remains as contested as it was in 1950.
- The AI winters (1974–80, 1987–93) followed one pattern — narrow success bred overconfident predictions — and expert systems in particular foundered on the "knowledge bottleneck," since human expertise is largely tacit.
- Searle's Chinese Room holds that syntax is never sufficient for semantics; Dennett's systems reply answers that understanding belongs to the whole system rather than the part, since individual neurons do not understand anything either.
- The 2025–26 turn: capability began scaling with inference-time compute and is now bought per query; the January 2025 open-weight release erased about $600 billion of Nvidia's market value in a day; and in 2026 capability itself began constraining release.
- Chalmers' hard problem: even a complete functional account leaves unexplained why processing is accompanied by subjective experience, so we may never know whether an AI that behaves as if conscious actually is.
- Russell's alignment problem: fixed-objective optimizers grow more dangerous as they grow more capable, because human values cannot be fully specified in advance.
- Floridi's "agency without intelligence": AI achieves goals without semantic understanding, and the twin risks are overestimating it (misplaced trust) and underestimating it (ignoring real harms at scale).
- Definition determines ethics: whether AI counts as a tool, a rational agent, or a potentially conscious system determines which ethical questions apply and who bears responsibility when things go wrong.